Defining good writing since 1997.Now shaping how AI writes.

AI still can't judge good writing on its own. Our managed expert editors, many with PhDs, define scoring rubrics, measure model output, and build gold SFT and preference data for AI labs and LLM product teams—so your models learn what good writing is.

500+Managed, QA-scored expert editors
<1%Applicant acceptance rate
3.7B+Words edited by human experts
75MBefore→after pairs from real editing work
10+ yrsShipping production AI models

Services

Define the standard. Measure against it. Build the data to beat it.

Rubrics that make writing quality measurable. Expert evaluations that show where your model stands. Training data that moves it forward.

Define

Set the standard

A quality bar you can apply, audit, and defend.

  • Scoring-rubric authoring: criteria, scales, anchor examples
  • Gold-set construction & annotator calibration
  • LLM-judge calibration: measure and close the human agreement gap
  • Annotation guidelines that transfer: your team or ours

Measure

Score the output

Expert scoring that shows exactly why output falls short.

  • Pairwise preference & side-by-side (SxS) ratings
  • Rubric-based scoring, criterion by criterion
  • Error annotation & failure analysis
  • Regression benchmarking across model versions

Build

Author the data

Expert-written, rights-cleared, ready to train on.

  • Gold edit-pair datasets with per-edit rationale
  • DPO/RLHF-ready SFT & preference data
  • ESL→fluent English datasets
  • Grammar-correction (GEC) gold sets

Use cases

Wherever you sit in the stack.

Whether you're a frontier lab or building on top of one, the service mix changes with how you build; the quality bar doesn't. We're deepest in the hardest writing: scientific, medical, and academic texts.

Frontier APIs

Whether RAG, agents, or straight generation, your product is the quality of the output. Expert evaluation shows that quality holds, even as the models underneath you change. Typical first engagement: recurring SxS evals that track quality across model updates.

Start withMeasureDefine

Hybrid stack

Frontier APIs for some tasks, your own models for others. Evaluate the whole system; train the parts you own. Typical first engagement: a system-wide evaluation, then data for what you train.

Start withMeasureBuild

Fine-tuning

You tune a foundation model to your domain, so your value is the adaptation layer. In-domain preference and edit-pair data is what improves it. Typical first engagement: a domain-calibrated rubric and the gold data to tune on.

Start withBuildMeasure

Pretraining

You own every stage of training, so your ceiling is your data. Expert-authored gold sets raise it where it counts: post-training. Typical first engagement: SFT gold sets and preference pairs for your next training run.

Start withBuildMeasure

Expertise

We don't just recognize good writing. We define it.

Since 1997, we've edited billions of words of academic, scientific, and professional writing. We can explain why good writing works, in criteria models can learn from.

A managed team of experts

Less than 1% of applicants make our roster, and many of our editors hold PhDs. Every expert is trained, calibrated to our standards, and QA-scored on every piece of live work. One managed, accountable team: no crowdworking marketplace underneath.

Researchers who ship models

Our team publishes the science of judging writing, including metrics such as the Scribendi Score (EMNLP 2021, reimplemented by other labs) and PEET (2025), which scores correction tools by the human effort needed to fix their output. Your rubrics come from people who ship language-quality models for a living.

Specialists in non-native English

English is the only language we work in, and we go deepest where it's hardest: non-native writing for scientific, academic, and professional contexts. Scribendi has refined ESL prose from clients worldwide since 1997; Edanz has spent two decades helping Japan's researchers publish in English.

ScribendiEdanz

335,000+ clients in 150+ countries since 1997, including 1600+ journals, universities, and academic societies. We run on the corpus, the editors, and the QA machinery behind those numbers.

Team

The team you actually get.

Our CTO and Lead AI Researcher work directly on every engagement. No handoff to a delivery team.

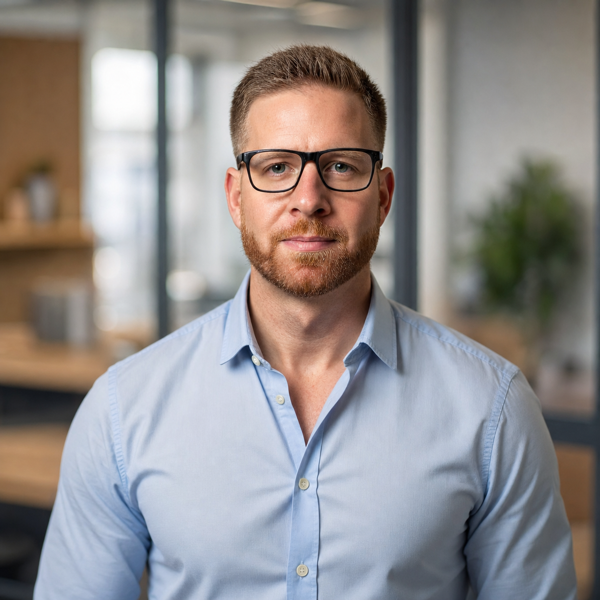
Bill Johnson

Chief Technology Officer

Publishes AI research and ships our production LLMs, GEC models, and evaluation methodology. Fifteen years at Scribendi. Built EditorWorks, the platform every engagement runs on, and led the technology organization through two acquisitions.

Connect on LinkedIn

Bill Johnson

Chief Technology Officer

Publishes AI research and ships our production LLMs, GEC models, and evaluation methodology. Fifteen years at Scribendi. Built EditorWorks, the platform every engagement runs on, and led the technology organization through two acquisitions.

Connect on LinkedIn

Design partner program

Start with a pilot. Build a partnership.

We're taking on a small group of design partners in 2026 and shaping our services around their needs.

Scope the pilot

  • A working session with our CTO and Lead AI Researcher
  • Start anywhere in your roadmap with a rubric, an eval, or a gold dataset
  • No obligation to take it any further

Run it at a fixed price

  • Scope, deliverable, price, and success metric locked in before we start
  • No open-ended contracts or hourly pricing
  • Approve a sample batch in weeks, not quarters, before full-volume delivery

Own the deliverable

  • Ships with QA evidence, including agreement scores and calibration records
  • Every datapoint traces to a named, QA-scored expert
  • You own it outright; we never reuse or train on your data

Scale into a partnership

  • Pilots run on 500+ vetted experts; partnerships scale into the thousands
  • A recurring engagement sized to your volume, still at a fixed price
  • Design partners shape where our services go next
Scope your pilot

Founding rates are subsidized through 2026. In return, we ask for a case study, anonymized if needed.

ISO 9001 certifiedNDAs standardNo training on your dataSOC 2 planned for 2027

Let's talk

Start a pilot.

Tell us what you're building. We'll come back with a pilot scoped to your stack: deliverable, price, and timeline.

  • A reply from our CTO within two business days
  • Fixed scope, fixed price, no obligation
  • NDAs before anything sensitive
  • We never train on your data
  • You own everything we deliver
  • Founding-cohort pricing, through 2026 only

Please add your name.

Please add a valid work email.

A sentence or two helps us shape the pilot.

White-label expert capacity.

If your product depends on expert judgment at scale, we can supply it under your spec, your brand, and your QA bar.

Discuss partnership terms

White label stays white label. NDAs first.